The best AI voice generators in November 2026 are ElevenLabs' Eleven v4, Alibaba's Qwen-Audio 3.1 Plus and Cartesia's Sonic 3.6, the three best-rated makers on the Artificial Analysis Speech Arena, where listeners pick the more natural of two clips. Google's Gemini 3.8 Flash TTS, first on the rival Design Arena, comes fourth, and Fish Audio's Drama 3 is the best model with open weights.
This guide ranks the top 10 text-to-speech models on blind listening tests, compares 15 on languages, voice cloning, speed and price per character, and covers open-source TTS, the best voice for each job and the services that shut down this year. Every score, price and date was checked on November 2, 2026. For pictures and video, see our rankings of the best AI image generators and the best AI video generators.
Top 10 AI voice generators in 2026, ranked
Ranked by the Artificial Analysis Speech Arena, the most widely cited text-to-speech leaderboard, with one model per maker. Only models you can use today count.
Eleven v4 and v4 Turbo (ElevenLabs): first and second on the arena four weeks after launch, in 90+ languages. Turbo is the faster, half-price version for voice agents.
Qwen-Audio 3.1 TTS Plus (Alibaba): third, and second when every model has to use the same cloned voices.
Sonic 3.6 (Cartesia): fourth, with first audio in under 90 ms and 44 languages. Built for real-time voice agents.
Gemini 3.8 Flash TTS (Google): fifth here and first on Design Arena, in 130+ languages, with a free tier in the Gemini API.
Fish Audio Drama 3 (Fish Audio): sixth and the highest-rated model with open weights, though its license limits commercial use.
Realtime TTS-2 (Inworld): eighth, a conversational model that reads the context of a dialogue, at $25 per million characters on demand.
Lightning V3.1 Pro (Smallest.ai): ninth, at $19.50 per million characters, with voice cloning from 5 seconds of audio.
Simba 3.2 (Speechify): eleventh and the cheapest model in this top 10, at $6 to $10 per million characters.
Breeze TTS 2 (BreezeBlue): an open-weight English and Chinese model, free for research only.
AssemblyAI-TTS-1 (AssemblyAI): the speech-to-text company's first voice model, launched October 27 at $15 per million characters.
How the top 10 placed on each board
Position of the same model on three boards. A dash means the board doesn't list that model.
# | Model | Artificial Analysis (each maker's own voices) | Artificial Analysis (same cloned voices) | Design Arena |
|---|---|---|---|---|
1 | Eleven v4 Turbo / v4 | 1 | 4 | 4 |
2 | Qwen-Audio 3.1 TTS Plus | 3 | 2 | — |
3 | Sonic 3.6 | 4 | 6 | — |
4 | Gemini 3.8 Flash TTS | 5 | 24 | 1 |
5 | Fish Audio Drama 3 | 6 | 12 | — |
6 | Realtime TTS-2 | 8 | 7 | — |
7 | Lightning V3.1 Pro | 9 | 11 | 17 |
8 | Simba 3.2 | 11 | 13 | — |
9 | Breeze TTS 2 | 13 | 28 | — |
10 | AssemblyAI-TTS-1 | 14 | 10 | — |
Places 9 and 10 are within a few points of Mistral's Voxtral 3 TTS (15th), well inside the margin of error. Google's model does better with its own voices than with cloned ones: Gemini 3.8 Flash TTS is fifth on the main board but 24th on the same-voice board.
Key numbers
ElevenLabs is back on top. Eleven v4 Turbo and v4, released September 28, hold first and second on Artificial Analysis, ahead of Alibaba and Cartesia.
The boards disagree on first place. Google's Gemini 3.8 Flash TTS leads Design Arena, HeyGen Voice leads Artificial Analysis' same-voice board, and Gradium leads the Hugging Face TTS Arena on early votes.
Prices vary more than 10-fold. In the top 10, API prices run from $6 to $10 per million characters (Speechify Simba 3.2) to $80 (Eleven v4). A million characters is about 17 hours of speech, at Rime's estimate of 1,000 characters a minute.
About 100 ms is the norm for voice agents. Cartesia, Inworld, AssemblyAI and Murf all say their models start speaking within about 100 ms, by their own measurements.
Open weights reach the top 10. Fish Audio Drama 3 (6th) and Breeze TTS 2 (13th) have open weights, but neither license allows free commercial use. The best model under a permissive license is Ant Group's Ming-3.0-tts (24th, MIT).
Some big names are leaving. OpenAI retires its text-to-speech API models on January 6, 2027, Hume shuts down its TTS API on November 13, and Resemble AI stopped selling voice AI in August.
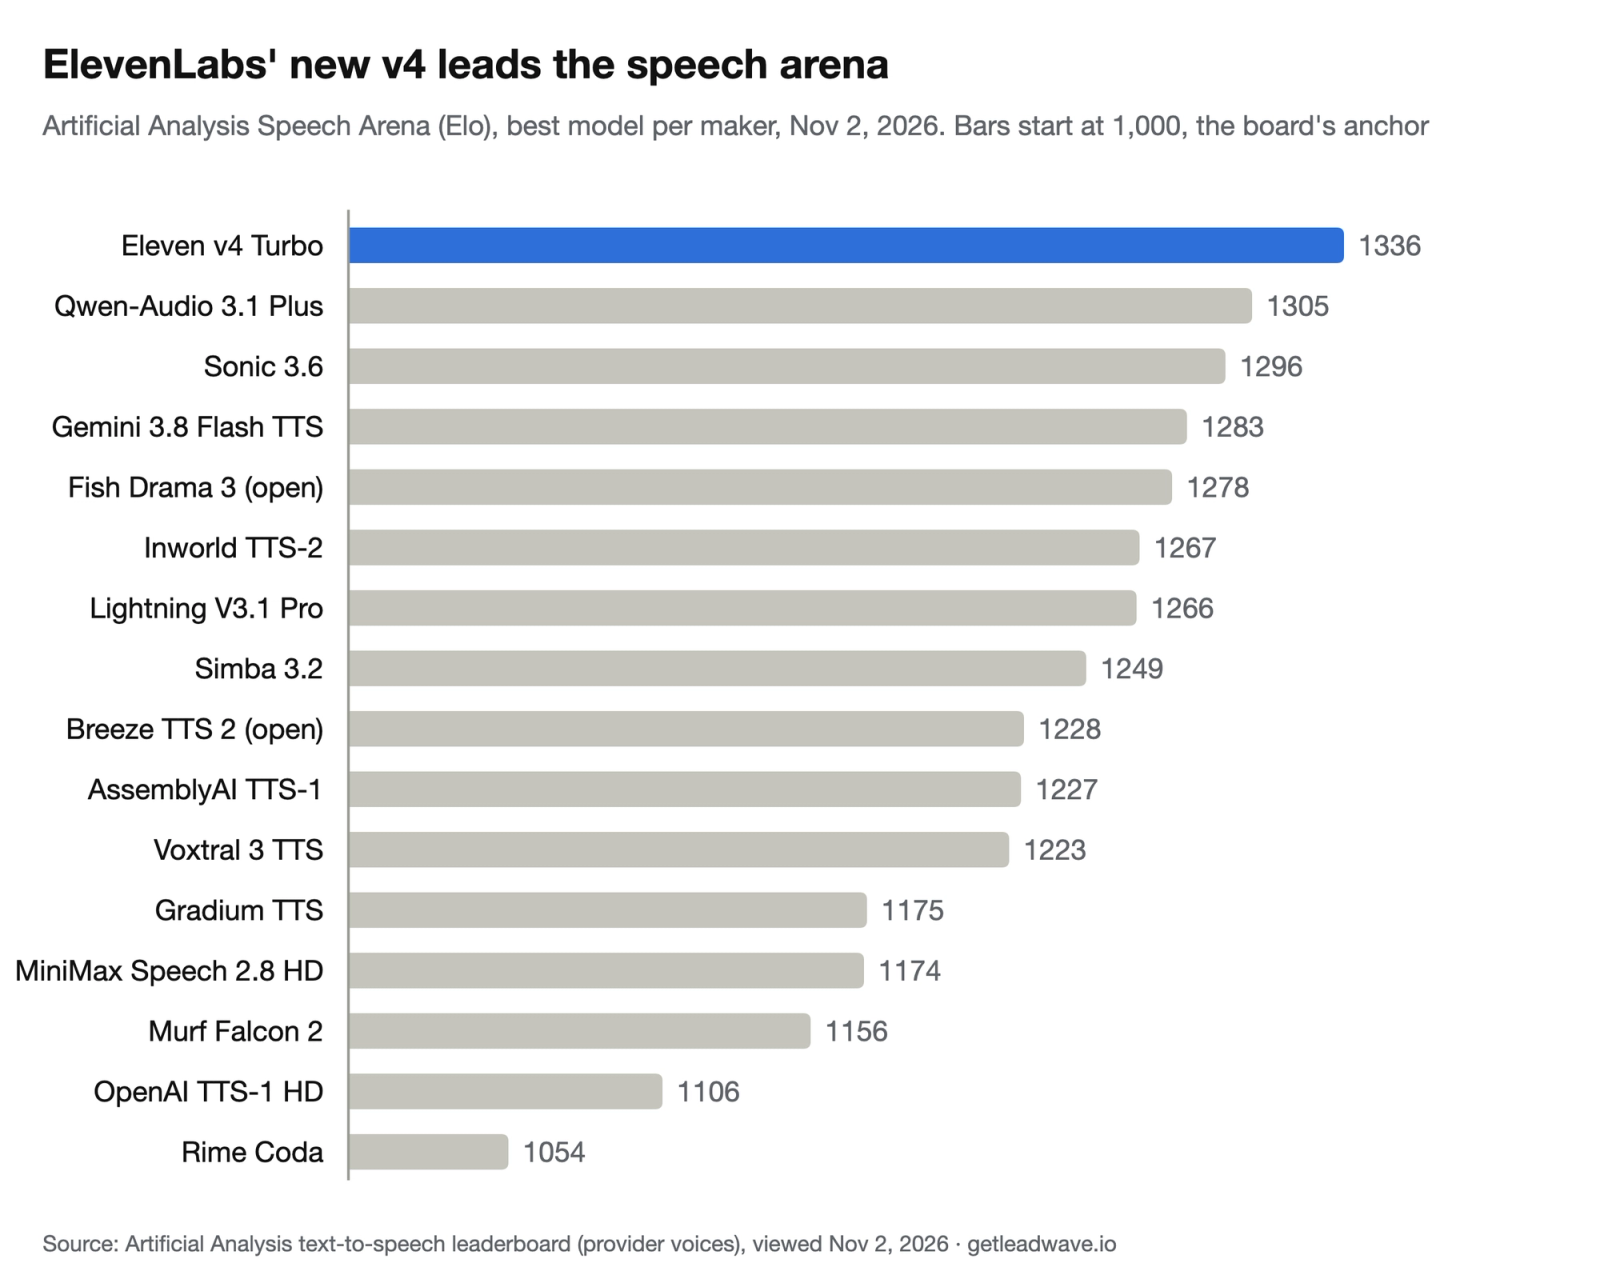
Text-to-speech leaderboards
TTS arenas play two clips of the same sentence from anonymous models and ask which sounds more natural. Thousands of votes become an Elo-style score: a higher score means the model wins more head-to-head comparisons. Artificial Analysis runs two boards, one where each maker uses its own voices and one where every model speaks with the same eight cloned voices. Design Arena and the Hugging Face TTS Arena run their own. Scores from different arenas aren't comparable. The large AI arena LMArena has no speech board.
Artificial Analysis, each maker's own voices
Top 15 of 100 models on the leaderboard, viewed November 2, 2026.
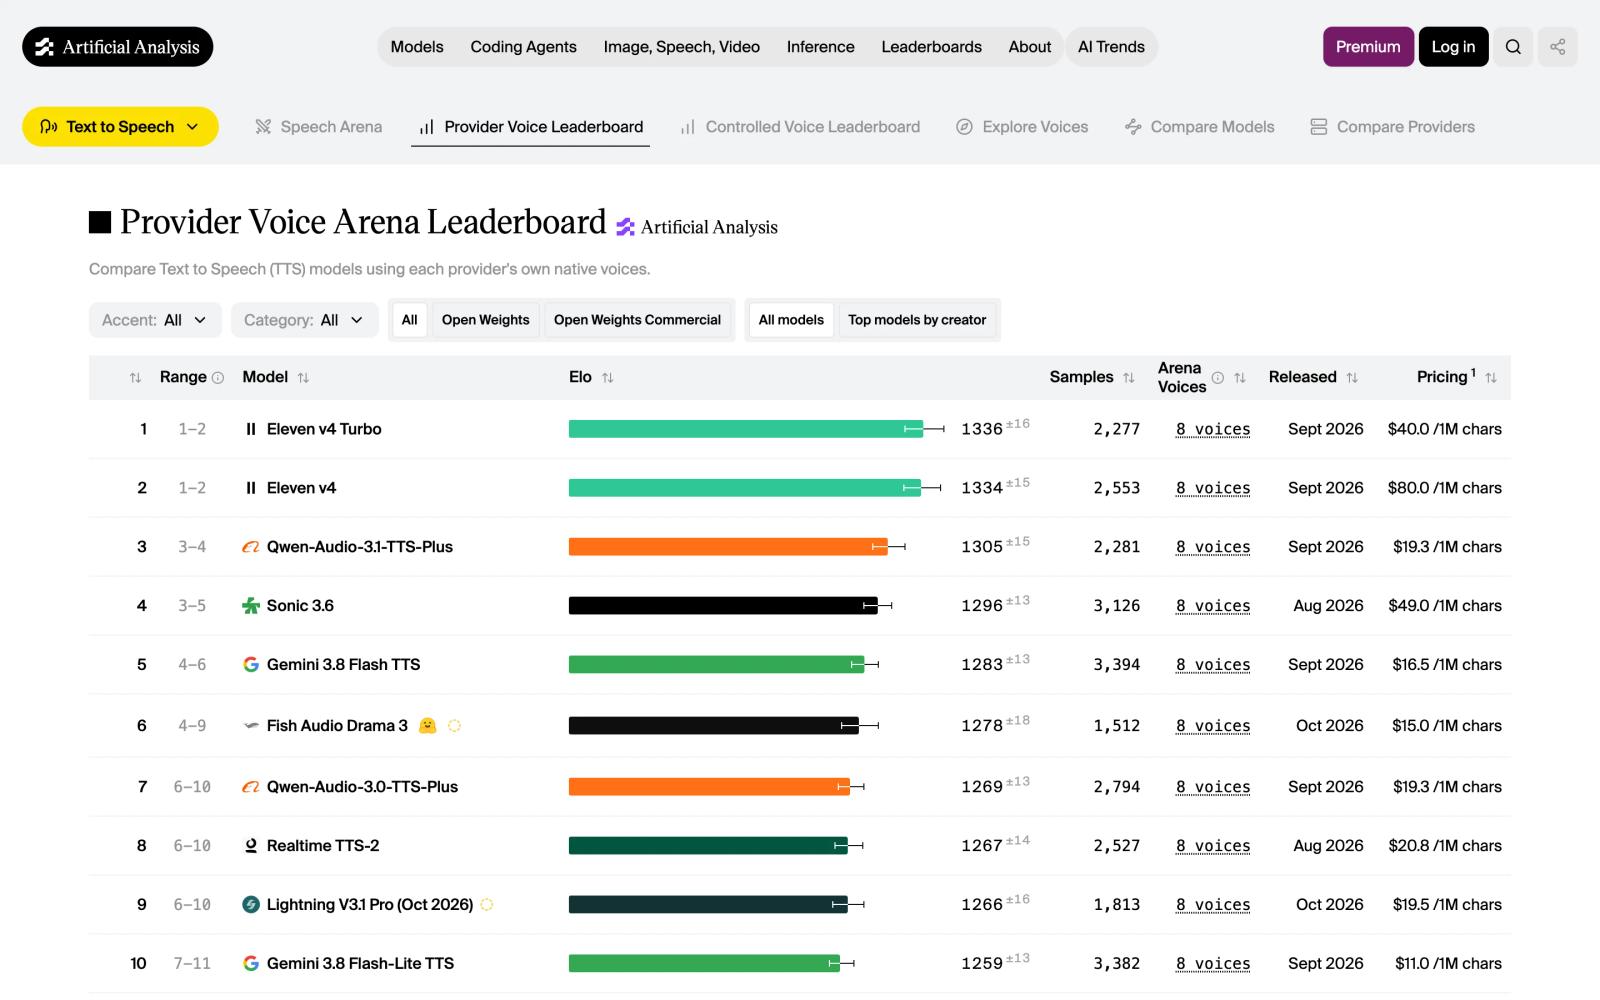
# | Model | Maker | Elo | Open weights |
|---|---|---|---|---|
1 | Eleven v4 Turbo | ElevenLabs | 1336 | No |
2 | Eleven v4 | ElevenLabs | 1334 | No |
3 | Qwen-Audio-3.1-TTS-Plus | Alibaba | 1305 | No |
4 | Sonic 3.6 | Cartesia | 1296 | No |
5 | Gemini 3.8 Flash TTS | 1283 | No | |
6 | Fish Audio Drama 3 | Fish Audio | 1278 | Yes |
7 | Qwen-Audio-3.0-TTS-Plus | Alibaba | 1269 | No |
8 | Realtime TTS-2 | Inworld | 1267 | No |
9 | Lightning V3.1 Pro | Smallest.ai | 1266 | No |
10 | Gemini 3.8 Flash-Lite TTS | 1259 | No | |
11 | Simba 3.2 | Speechify | 1249 | No |
12 | Fish Audio Drama 3 Preview | Fish Audio | 1240 | Yes |
13 | Breeze TTS 2 | BreezeBlue | 1228 | Yes |
14 | AssemblyAI-TTS-1 | AssemblyAI | 1227 | No |
15 | Voxtral 3 TTS | Mistral | 1223 | No |
Artificial Analysis, same cloned voices
Top 10 of 49 models on the same-voice leaderboard, viewed November 2, 2026. It takes the voice out of the comparison, so it tests the model rather than its voice catalog.
# | Model | Maker | Elo |
|---|---|---|---|
1 | HeyGen Voice | HeyGen | 1193 |
2 | Qwen-Audio-3.1-TTS-Plus | Alibaba | 1181 |
3 | HeyGen Voice Turbo | HeyGen | 1180 |
4 | Eleven v4 | ElevenLabs | 1156 |
5 | Eleven v4 Turbo | ElevenLabs | 1156 |
6 | Sonic 3.6 | Cartesia | 1147 |
7 | Realtime TTS-2 | Inworld | 1146 |
8 | Qwen-Audio-3.0-TTS-Plus | Alibaba | 1125 |
9 | Sonic 3.5 | Cartesia | 1114 |
10 | AssemblyAI-TTS-1 | AssemblyAI | 1108 |
Design Arena
Top 10 of 34 models on the TTS leaderboard, updated November 2, 2026. It includes models Artificial Analysis lacks, such as Microsoft's MAI-Voice-2 and OpenAI's GPT-4o mini TTS, but not Alibaba's Qwen-Audio, Cartesia's Sonic 3.6 or Fish Audio's models.
# | Model | Maker | Elo |
|---|---|---|---|
1 | Gemini 3.8 Flash TTS | 1457 | |
2 | Gemini 3.1 Flash TTS | 1426 | |
3 | Gemini 2.5 Pro TTS | 1382 | |
4 | Eleven v4 Turbo | ElevenLabs | 1359 |
5 | Eleven v4 | ElevenLabs | 1353 |
6 | Gemini 2.5 Flash TTS | 1339 | |
7 | Eleven v3 | ElevenLabs | 1260 |
8 | Grok TTS | xAI | 1222 |
9 | GPT Realtime 2 | OpenAI | 1203 |
10 | GPT-4o mini TTS | OpenAI | 1187 |
The community-run Hugging Face TTS Arena is led by Gradium's October model on early votes, followed by an anonymous entry called Aurora and Inworld's TTS models. It ranks models by the low end of their confidence range, so its order doesn't strictly follow the scores.
The 15 best text-to-speech models compared
API list prices per million characters from each maker's pricing page, checked November 2, 2026. Speed is time to first audio as each maker measures it, so the figures aren't directly comparable.
Model | Maker | Languages | Voice cloning | Time to first audio | API price per 1M characters | Open weights |
|---|---|---|---|---|---|---|
Eleven v4 / v4 Turbo | ElevenLabs | 90+ | Yes, from 10 s | About 150 ms (Turbo) | $80; Turbo $40 | No |
Qwen-Audio-3.1-TTS-Plus | Alibaba | Several (not stated) | Yes | Not published | $30 ($20 in mainland China) | No |
Sonic 3.6 | Cartesia | 44 | Yes, from 10 s | Under 90 ms | $37 to $50, by plan | No |
Gemini 3.8 Flash TTS | 130+ | Yes, 10 to 30 s plus consent | Not published | About $16 (Artificial Analysis' conversion; Google bills per audio token); free tier | No | |
Fish Audio Drama 3 | Fish Audio | About 80 | Yes | Not published | $50 ($10 until Nov 12) | Yes, restricted |
Realtime TTS-2 | Inworld | 100+ | Yes, from a few seconds | 100 ms (P90, server) | $25, down to $5 at volume | No |
Lightning V3.1 Pro | Smallest.ai | 31 | Yes, from 5 s | 200 ms | $19.50 | No |
Simba 3.2 | Speechify | English (Simba 3.5: 48) | Yes, paid plans | 56 ms median | $6 to $10 | No |
Breeze TTS 2 | BreezeBlue | English, Chinese | Yes | Not published | Hosted API, paid plans | Yes, non-commercial |
AssemblyAI-TTS-1 | AssemblyAI | 6 | Yes, instant | 90 ms | $15 | No |
Voxtral 3 TTS | Mistral | 35+ | Yes | Not published | $13 | No |
Speech 2.8 HD / Turbo | MiniMax | 40 | Yes, from 10 s | Not published | $100; Turbo $60 | No |
Gradium TTS | Gradium | 5 | Yes, from 10 s | Under 50 ms (Gradium's figure) | $36 to $58, by plan | Phonon (on-device) |
Falcon 2 | Murf | 35+ | Enterprise, from 10 s | 95 ms median | $10 | No |
Coda | Rime | 10 | Enterprise | Under 100 ms plus network | About $40 to $50 ($0.04 to $0.05 a minute) | No |
The top 10 voice models in detail
1. Eleven v4
Eleven v4 and Eleven v4 Turbo, released September 28, 2026, hold first and second place on Artificial Analysis and fourth and fifth on Design Arena. Both speak 90+ languages, and instant voice clones need 10 seconds of audio. ElevenLabs measured v4 Turbo at about 150 ms median time to first speech, network excluded. ElevenLabs reported more than $330 million in annual recurring revenue at the end of 2025 and was valued at $22 billion in an employee share sale on September 30, 2026.
API price: $0.08 per 1,000 characters for v4, $0.04 for v4 Turbo (ElevenLabs)
Free: 10,000 credits a month, without voice cloning
2. Qwen-Audio 3.1 TTS Plus
Qwen-Audio 3.1 TTS Plus is Alibaba's premium speech model in Alibaba Cloud Model Studio, listed in its release notes on October 21, 2026. It is third on Artificial Analysis' main board and second when every model uses the same cloned voices. It clones and designs voices and takes inline tags such as [laughing] and [cough]. Its predecessor, Qwen-Audio 3.0 TTS Plus, took first place on the board in July, The Decoder reported.
API price: $0.30 per 10,000 characters internationally, $0.20 in mainland China (Alibaba Cloud)
Free: 10,000 characters in the Singapore region
3. Sonic 3.6
Sonic 3.6, released August 27, 2026, is Cartesia's real-time model for voice agents: first audio in under 90 ms, 44 languages and instant cloning from 10 seconds of audio. Cartesia came out of Stanford's AI lab in 2023 and builds its models on state-space architectures.
API price: 1 credit per character, $37 to $50 per million depending on plan
Free: 20,000 credits a month (about 27 minutes), without voice cloning
4. Gemini 3.8 Flash TTS
Gemini 3.8 Flash TTS, generally available since September 22, 2026, is first on Design Arena and fifth on Artificial Analysis. It speaks 130+ languages with one or two speakers per request, and can design a voice from a text description or copy one from a 10 to 30 second clip plus a consent recording. Style instructions and inline tags like <sigh> control delivery. Its lighter sibling, Gemini 3.8 Flash-Lite TTS, is tenth on Artificial Analysis.
API price: $9 per million audio output tokens through December 31, 2026 (about $0.0135 a minute), doubling on January 1, 2027 (Google)
Free: a free tier in the Gemini API and Google AI Studio
5. Fish Audio Drama 3
Fish Audio Drama 3, released October 13, 2026, is the highest-rated model with open weights on Artificial Analysis. It is a 35-billion-parameter mixture-of-experts model that uses 3 billion per token, in about 80 languages, and Fish Audio calls it its most emotive model. Its community license allows commercial use only for companies with under $500,000 in yearly revenue, and never as a hosted service. Fish Audio, based in Palo Alto, raised a $52 million seed round in July at $21 million in annual recurring revenue.
API price: $50 per million characters, $10 until November 12
Also: Fish Audio S2.1 Pro costs $15 per million bytes of text; a free version runs until November 30
6. Realtime TTS-2
Realtime TTS-2, generally available since August 31, 2026, is Inworld's conversational model: it takes the dialogue so far into account when it speaks. It is eighth on Artificial Analysis and seventh on the same-voice board. Inworld's docs give 100 ms time to first byte at P90 on its servers, and 20 ms for the smaller TTS-2 Flash.
API price: $25 per million characters on demand, down to $5 at enterprise volume; Flash $15 (Inworld)
Free: a pay-as-you-go plan with no monthly fee
7. Lightning V3.1 Pro
Lightning V3.1 Pro is Smallest.ai's highest-quality model; an October 2026 version is ninth on Artificial Analysis and tenth on the Hugging Face arena. It covers 31 languages, clones a voice from 5 seconds of audio, and its model card gives 200 ms time to first byte. The San Francisco company, founded by CEO Sudarshan Kamath, raised a $13 million Series A in July 2026; its customers include RingCentral and Truecaller.
API price: $0.195 per 10,000 characters (Smallest.ai)
Free: $10 in credits
8. Simba 3.2
Simba 3.2, Speechify's English model from July 2026, is eleventh on Artificial Analysis and the cheapest model in this top 10. Speechify measured 56 ms median time to first audio on its own servers. Its July launch claimed first place on the board; it has since slipped. Simba 3.5, released October 21, covers 48 languages under one model ID but isn't rated yet.
API price: $6 to $10 per million characters, by plan; Simba 3.5 $12 to $20, half price until November 22 (Speechify)
Free: 500,000 characters a month on the API (250,000 for Simba 3.5 after November 21)
9. Breeze TTS 2
Breeze TTS 2, released August 25, 2026, is a 3-billion-parameter open-weight model that speaks English and Chinese from one checkpoint. It designs voices from a text description, clones from reference audio and handles inline sounds like laughter. The weights and anything you generate with them yourself are for research and non-commercial use only; audio from BreezeBlue's hosted service can be used commercially on a paid plan.
Price: free to download for research; paid plans for the hosted API
10. AssemblyAI-TTS-1
AssemblyAI-TTS-1, generally available since October 27, 2026, is the first speech model from AssemblyAI, best known for speech-to-text. It is built for voice agents, speaks English, Spanish, French, German, Italian and Portuguese, and AssemblyAI quotes 90 ms to first audio in production. It includes instant voice cloning; fine-tuned cloning isn't available yet.
API price: $15 per million characters
5 more voice models worth knowing
Voxtral 3 TTS
Voxtral 3 TTS, released October 20, 2026 with Mistral's Voxtral 3 voice-agent kit, speaks 35+ languages and 50+ dialects and supports zero-shot and professional cloning. It is 15th on Artificial Analysis and 13th on Design Arena, a near tie with places 9 and 10. Mistral's first speech model, Voxtral TTS from March 2026, has open weights under a non-commercial license.
API price: $13 per million characters
MiniMax Speech 2.8
MiniMax Speech 2.8, released January 23, 2026, speaks 40 languages with seven emotions and sound tags such as (laughs) and (breath), and clones a voice from 10 seconds of audio. The HD version is 27th on Artificial Analysis and eighth on the Hugging Face arena.
API price: $100 per million characters for HD, $60 for Turbo
Gradium
Gradium is a Paris start-up spun out of the non-profit lab Kyutai in September 2025 and led by CEO Neil Zeghidour. Its seed round reached $100 million in July 2026 with NVIDIA. It updates its TTS model every few weeks: the September version is 26th on Artificial Analysis, and the October version leads the Hugging Face arena on early votes. It covers five languages and clones from 10 seconds. In October it released Phonon, tiny models that run on a phone; the 31-million-parameter English model is open under Apache 2.0.
API price: 1 credit per character, $36 to $58 per million by plan
Free: 45,000 credits a month (about an hour of speech)
Murf Falcon 2
Murf Falcon 2, released August 20, 2026, is Murf's model for voice agents, with 35+ languages and 150+ voices. Murf reports a 95 ms median time to first audio in production. It is 29th on Artificial Analysis and one of the cheapest APIs here.
API price: 1 cent per 1,000 characters ($10 per million); voice cloning on enterprise plans
Rime Coda
Rime Coda is the main model of Rime, a San Francisco company that voices enterprise phone calls; Coda replaced Rime's Arcana models on August 15, 2026. It speaks 10 languages on the cloud API, and Rime gives under 100 ms model latency plus 25 to 50 ms of network time. Coda is 66th on Artificial Analysis, but Rime is built for call centers rather than listening contests: TechCrunch reported it handles over 100 million calls a month when it raised a $24 million Series A in July.
API price: $0.05 a minute, or $0.04 at scale
Free: $50 of usage every month
Voice models from big tech
OpenAI is retiring its text-to-speech API: tts-1, tts-1-hd and gpt-4o-mini-tts shut down on January 6, 2027 (OpenAI). It points developers to its realtime voice models and sells GPT-Live 1, a model that listens and speaks at the same time, at $0.05 a minute. TTS-1 HD is 42nd on Artificial Analysis.
Microsoft makes MAI-Voice-2.1 (October 2026, 23 languages, $22 per million characters) and a faster Flash version at $15. MAI-Voice-2 is 12th on Design Arena; Azure's HD voices are 32nd on Artificial Analysis.
xAI, now part of SpaceX, sells a Grok TTS API with 20 languages and 28 voices at $15 per million characters. It is 8th on Design Arena and 28th on Artificial Analysis.
Amazon sells Polly's generative voices at $30 per million characters (59th on Artificial Analysis) and Nova 2.5 Sonic, a speech-to-speech model for voice apps on Bedrock, launched October 5, 2026.
Deepgram launched Flux TTS on August 12, 2026, English only, with first audio in as little as 80 ms, at $45 per million characters; its older Aura-2 costs $30.
Best open-source text-to-speech models
Fish Audio Drama 3: the highest-rated open model (6th on Artificial Analysis), but commercial use is limited to companies under $500,000 in revenue and never as a hosted service.
Ming-3.0-tts (Ant Group): a 0.5B model under MIT, 24th on Artificial Analysis; the best-rated open model under a permissive license.
Qwen3-TTS (Alibaba): 0.6B and 1.7B models under Apache 2.0 from January 2026, in 10 languages, with voice cloning from 3 seconds of audio.
Chatterbox (Resemble AI): MIT-licensed; Multilingual V3 (June 2026) speaks 23 languages, and the smaller Turbo and Nano versions target real-time and on-device use.
ZONOS2 (Zyphra): an 8B mixture-of-experts model with 900M active parameters under Apache 2.0, released June 2026.
Kokoro-82M: an 82-million-parameter model under Apache 2.0 from January 2025, the cheapest model on Artificial Analysis and still one of the most popular on Hugging Face.
Tiny models for devices: Kyutai's Pocket TTS (100M, runs on a CPU) and Gradium's Phonon (31M, Apache 2.0).
Breeze TTS 2 (BreezeBlue): 13th on Artificial Analysis, English and Chinese, research and non-commercial use only.
Best AI voice generator by use case
Best overall: Eleven v4, with Qwen-Audio 3.1 TTS Plus and Cartesia Sonic 3.6 close behind.
Best for voice agents: Eleven v4 Turbo, Cartesia Sonic 3.6, Inworld Realtime TTS-2, Smallest.ai Lightning and AssemblyAI-TTS-1; Rime for high-volume phone calls.
Most languages: Gemini 3.8 Flash TTS (130+), Eleven v4 (90+) and Fish Audio Drama 3 (about 80).
Best value: Speechify Simba 3.2 ($6 to $10 per million characters), Murf Falcon 2 ($10), Voxtral 3 TTS ($13) and AssemblyAI-TTS-1 ($15).
Voice cloning from the shortest clip: Smallest.ai Lightning (5 seconds) and, open source, Qwen3-TTS (3 seconds).
Expressive narration: Eleven v4 and Fish Audio Drama 3.
Best free: Gemini's free API tier, Speechify's 500,000 free characters a month, ElevenLabs' 10,000 credits a month and Rime's $50 of monthly usage; open models are free to run yourself.
Self-hosting: Ming-3.0-tts, Qwen3-TTS and Chatterbox for commercial use; Kokoro, Pocket TTS and Phonon for small devices.
Music: a different category; AI music generators such as Suno, Udio and Google's Lyria make songs, not speech.
What changed in 2026
Model or company | What happened | When |
|---|---|---|
Hume AI | Google DeepMind reportedly licensed its technology and hired its founder; Hume later announced the end of its TTS API | Jan 2026; API ends Nov 13, 2026 |
Mistral | Released its first speech model, Voxtral TTS, then Voxtral 3 | Mar and Oct 2026 |
Resemble AI | Stopped selling voice AI to new customers to focus on deepfake detection; Chatterbox stays open | Aug 13, 2026 |
Rime | Retired its Arcana models in favour of Coda | Aug 15, 2026 |
Gemini 3.8 Flash TTS and Flash-Lite TTS generally available; prices double on January 1, 2027 | Sep 22, 2026 | |
ElevenLabs | Launched Eleven v4 and v4 Turbo, which took first and second on Artificial Analysis | Sep 28, 2026 |
OpenAI | Deprecated its text-to-speech API models, which shut down on January 6, 2027 | Oct 1, 2026 |
Fish Audio | Released Drama 3 with open weights | Oct 13, 2026 |
Block | Announced Dessa, a speech-to-speech model that isn't public yet | Oct 2026 |
PlayHT and LOVO | PlayHT's sites no longer load after Meta bought it in 2025; LOVO's site has been offline since at least August | 2026 |
FAQ
What is the best AI voice generator in 2026? ElevenLabs' Eleven v4 and v4 Turbo lead the Artificial Analysis Speech Arena, ahead of Alibaba's Qwen-Audio 3.1 TTS Plus and Cartesia's Sonic 3.6. Google's Gemini 3.8 Flash TTS leads Design Arena.
What is the most realistic text-to-speech? Arena votes measure exactly that: listeners pick whichever of two clips sounds more natural. On Artificial Analysis, Eleven v4 Turbo wins the most of those comparisons.
What is the best free text-to-speech? Google's Gemini API has a free tier for Gemini 3.8 Flash TTS, Speechify's API gives 500,000 free characters a month and ElevenLabs 10,000 credits. Open models such as Kokoro, Qwen3-TTS and Chatterbox are free to run on your own hardware.
What is the best open-source TTS model? Fish Audio Drama 3 rates highest, but its license limits commercial use. For commercial projects, Ant Group's Ming-3.0-tts (MIT), Alibaba's Qwen3-TTS (Apache 2.0) and Resemble AI's Chatterbox (MIT) are the strongest options; Kokoro is the best tiny model.
What is the fastest text-to-speech for voice agents? By their makers' own measurements, Inworld's TTS-2 Flash (20 ms on its servers), Cartesia Sonic 3.6 (under 90 ms), AssemblyAI-TTS-1 (90 ms) and Murf Falcon 2 (95 ms median). Each company measures differently, so test with your own setup.
How much does a text-to-speech API cost? Among these 15 models, $6 to $100 per million characters. At about 1,000 characters a minute, a million characters is roughly 17 hours of speech.
Is OpenAI's text-to-speech being discontinued? Yes. OpenAI deprecated tts-1, tts-1-hd and gpt-4o-mini-tts on October 1, 2026, and they shut down on January 6, 2027. It recommends its realtime voice models instead.
What is Dessa, Jack Dorsey's voice model? Dessa is a speech-to-speech model from Block, the company Dorsey runs, announced in October 2026. It listens and talks at the same time, and Block says it runs on consumer GPUs. There is no public access yet (TechCrunch). It is separate from Buzz, Dorsey's chat app for teams and AI agents.
Which voice AI services shut down in 2026? Hume AI ends its TTS API on November 13, 2026, Resemble AI stopped selling voice AI to new customers in August, PlayHT's sites no longer load after Meta bought it, and LOVO's website has been offline since at least August.
How this list was built
The list: the companies tagged as text-to-voice AI models in LeadWave's database, plus the makers that lead the speech leaderboards. Speech-to-text, sound-effect and music companies are left out, as are apps and platforms that host other companies' models.
The ranking: position on the Artificial Analysis Speech Arena (each maker's own voices, viewed November 2, 2026), one model per maker, counting only models you can use today. It is checked against Artificial Analysis' same-voice board, Design Arena (November 2, 2026) and the Hugging Face TTS Arena.
The facts: release dates, languages, cloning, prices and licenses checked on November 2, 2026 against each company's own pages and pricing pages, or a major news outlet. Speed figures are the makers' own.
Selling to AI companies?
LeadWave's list of AI companies covers 9,000 AI companies with CEO details. See also the best AI video generators and our list of AI labs.
About this list
Compiled by LeadWave from the public text-to-speech leaderboards and company announcements, checked November 2, 2026.